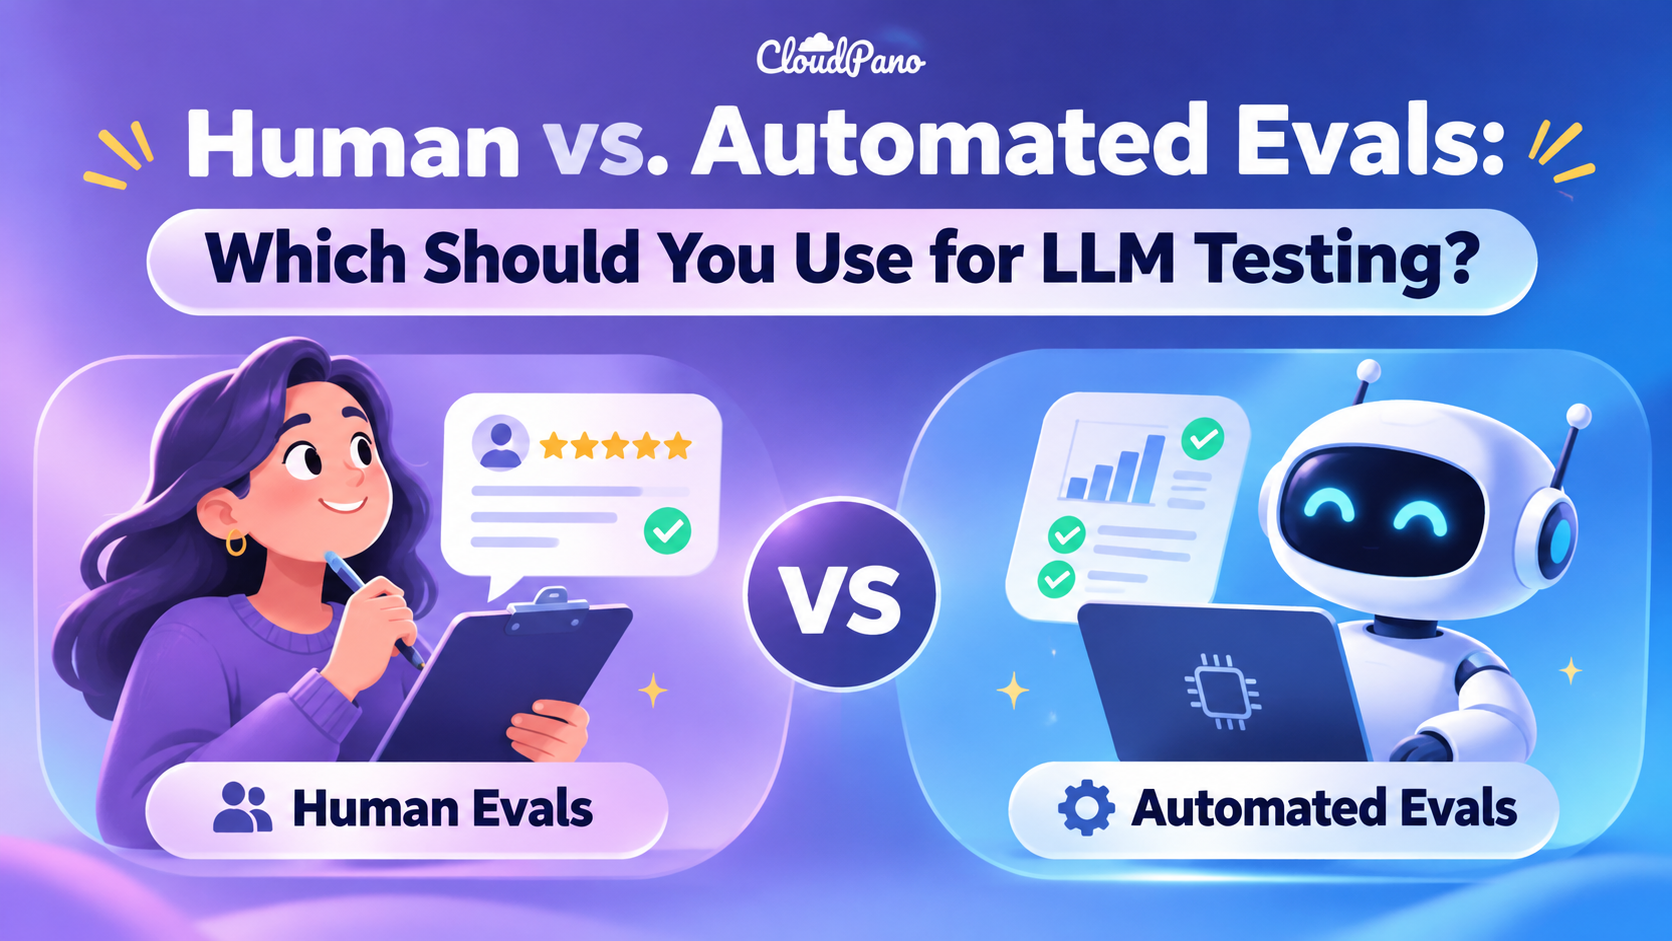
Human vs. Automated Evals: Which Should You Use for LLM Testing?
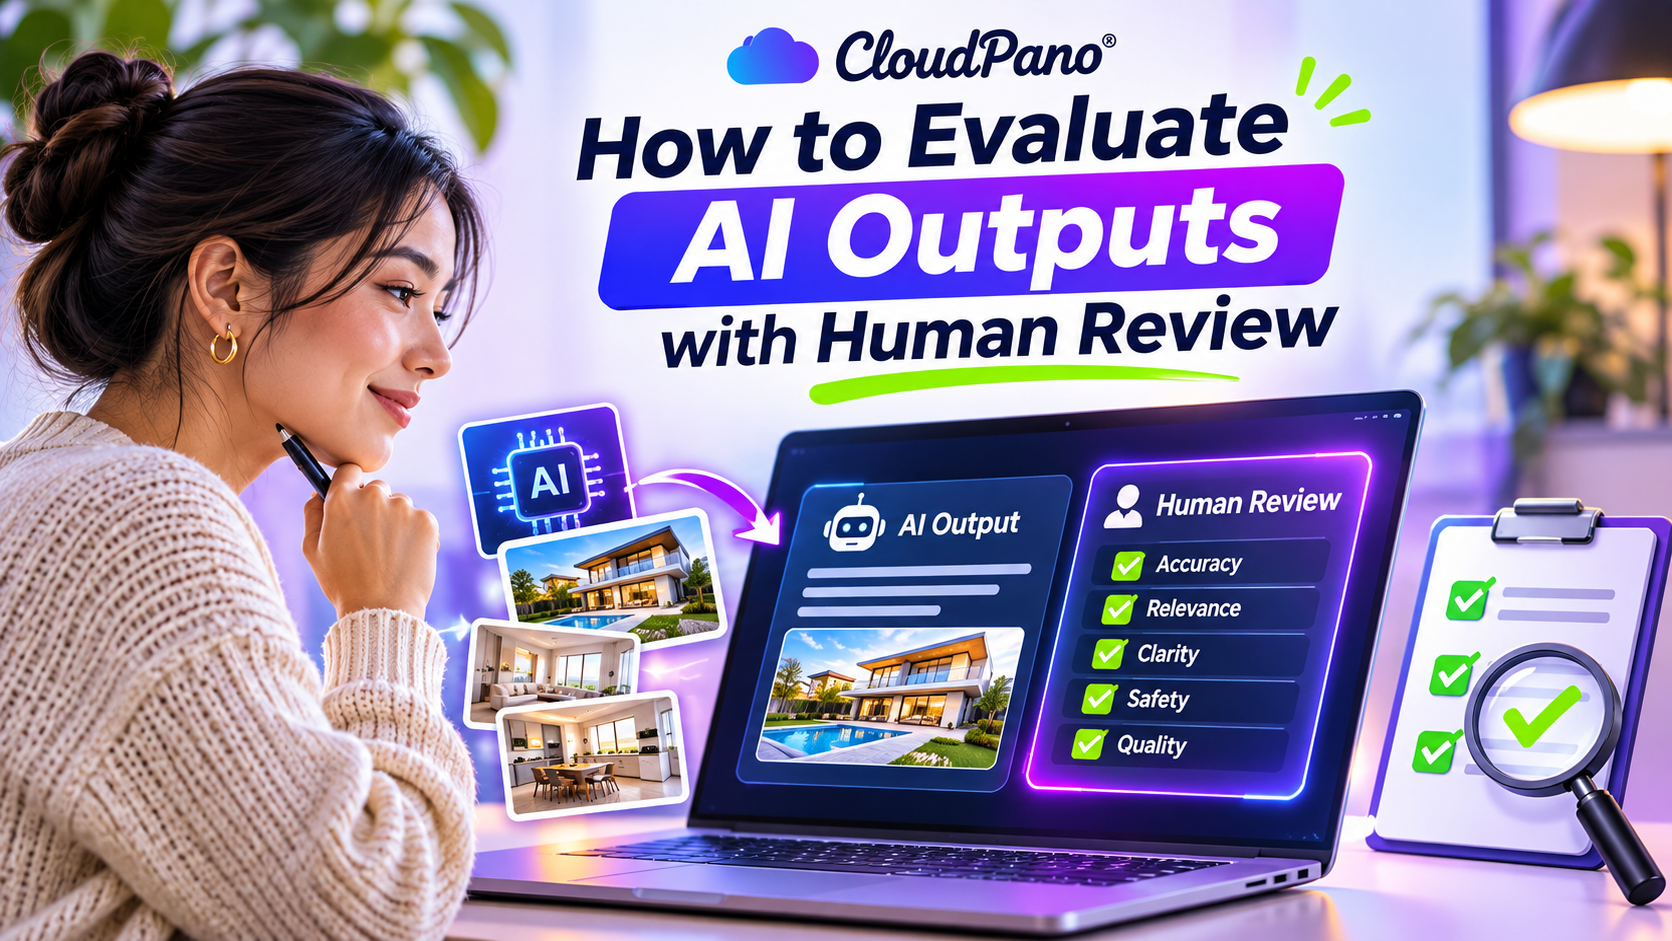
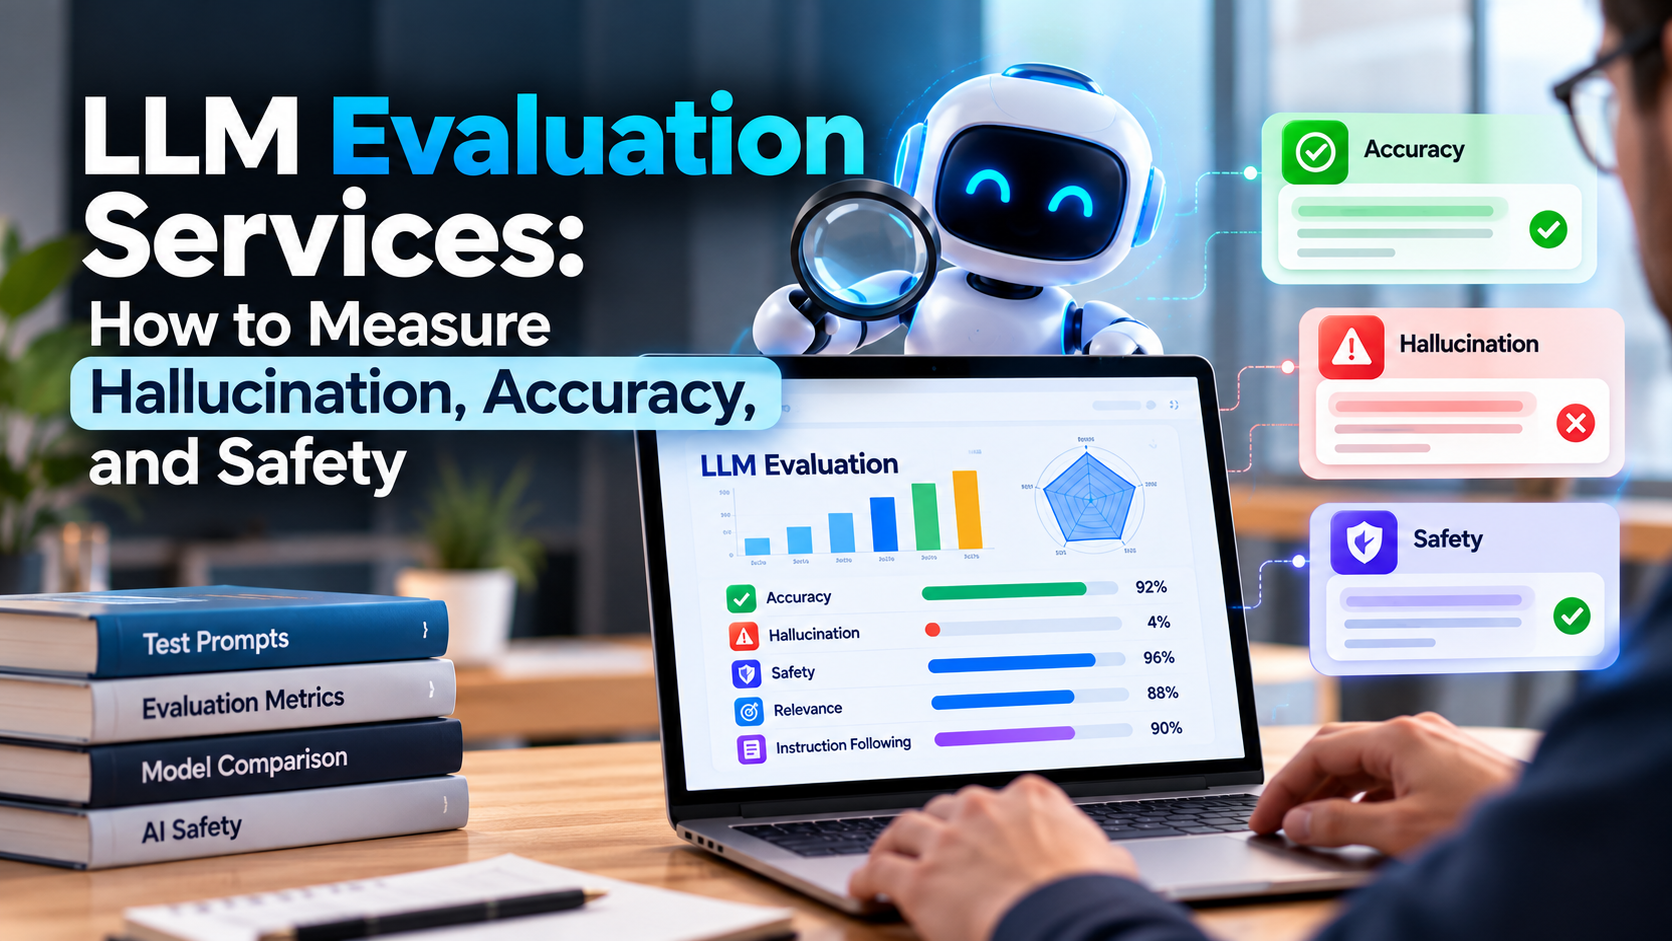
Human and automated evaluations play essential roles in measuring the accuracy, safety, and quality of large language model (LLM) outputs. This guide explores the key differences between human vs automated evals, including their strengths, limitations, costs, and scalability. Learn when to use human reviewers, when automated testing works best, and how combining both approaches creates a more reliable LLM evaluation strategy.