Metadata turns raw footage into training data. Labels say which action happens, timestamps say when it starts and stops, and IDs say who did it and where. That lets models learn actions, lets teams split data fairly and filter it, and lets buyers check consent and license. EPIC-KITCHENS-100's denser labeling pipeline captured 54% more actions per minute.
When the EPIC-KITCHENS team rebuilt its labeling pipeline, its kitchen video ended up with 54% more actions per minute and 128% more action segments than the first version, per the EPIC-KITCHENS-100 paper. The difference was in how actions were labeled.
That is the quiet truth about any human activity recognition dataset. Hours of video are only the raw material. What a model can actually learn depends on the information attached to each clip: what is happening, when it starts and stops, and who is doing it. This guide explains what that metadata is, how the best-known public datasets use it, and what to ask for before you buy or build.
Metadata is the information that describes each video rather than the pixels themselves. In a training dataset it usually answers three questions: what is happening, when it happens, and who or where it was recorded.
A simple way to see the difference is to compare two versions of the same 10-minute clip.
The first is footage. The second is a dataset. That chopping example comes straight from Ego4D's annotation guidelines, where annotators pause the video, mark the window an action covers, and type a short sentence describing it.
If you're new to this kind of footage, our guide to real-world video data explains why it matters for multimodal AI in the first place.
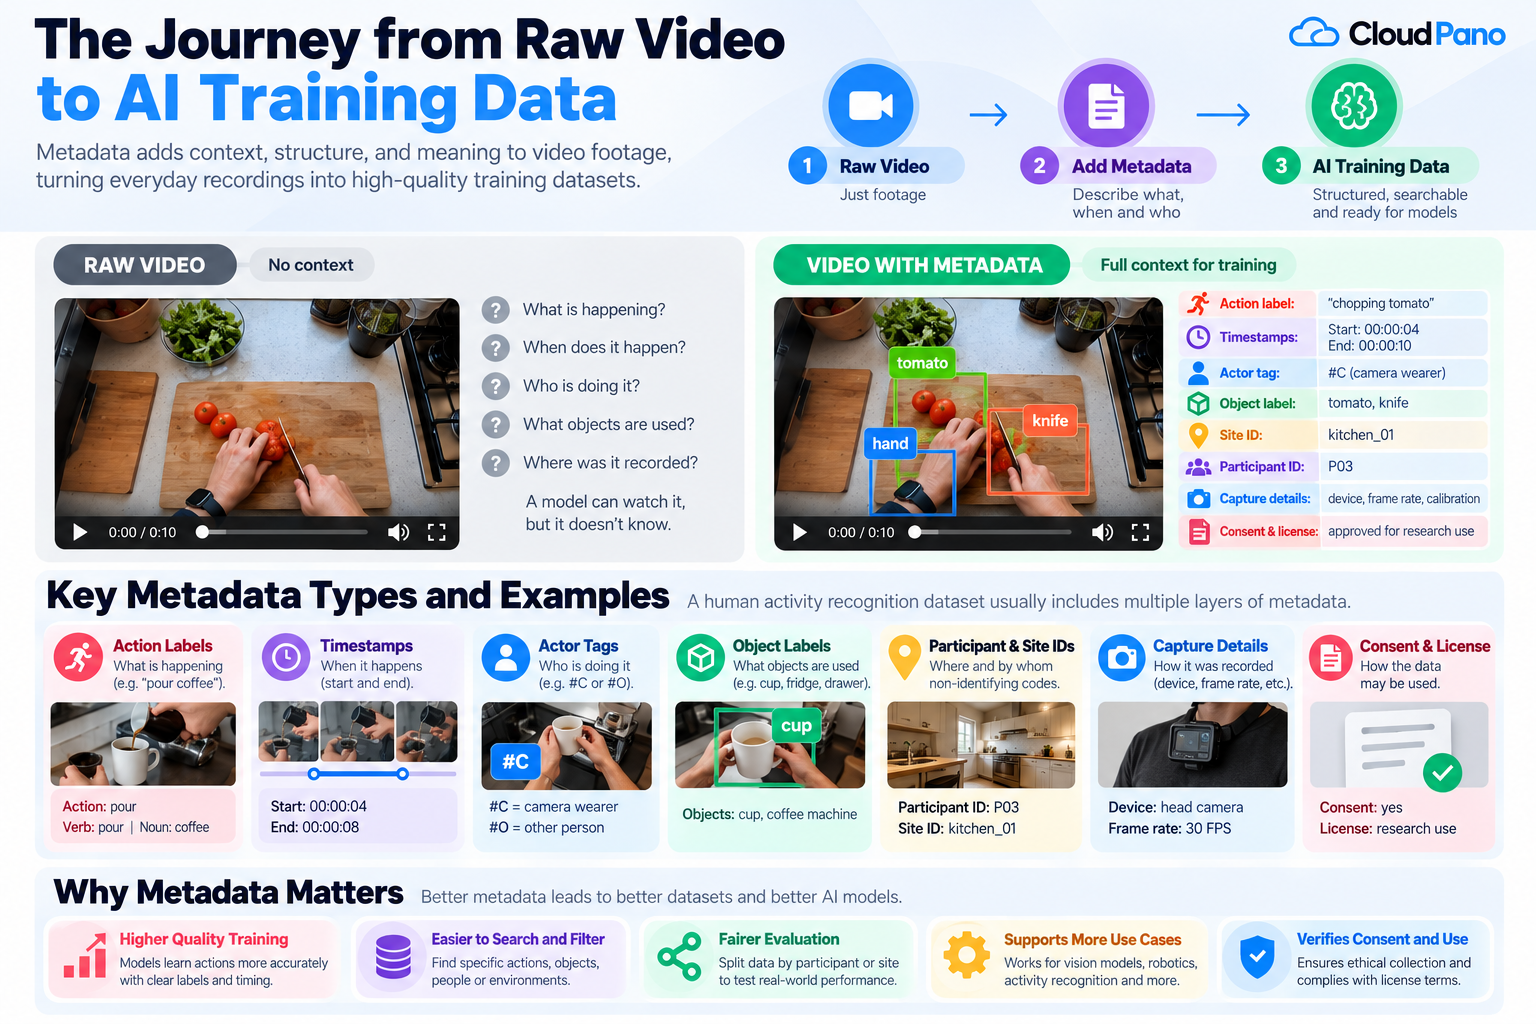
At minimum, a human activity recognition dataset needs an action label and a start and end time for every action. Everything else adds value on top: who did it, where, with which objects, on which device.
Here are the layers that show up again and again in serious datasets:
Our article on daily activity video datasets shows how these labels look on everyday tasks like making coffee or folding laundry.
Timestamps and action labels tell the model exactly which frames to learn from. Without them, a model sees long stretches of video with no idea where "open fridge" ends and "take milk" begins.
The EPIC-KITCHENS-100 numbers show how much this matters. The team didn't just film more; it changed how actions were narrated and marked in time. The paper reports 100 hours of video, 20 million frames and 90,000 actions across 700 videos in 45 kitchens. Its denser pipeline found more of the small, fast actions that a coarser process would have missed.
Ego4D took a similar approach at a much larger scale. Its annotation guidelines list all 3,670 hours as narrated, with a timestamped sentence for each new action and a one-to-three-sentence summary for each clip.
Yes. Good metadata often outlives the task it was made for. Text narrations in particular can be turned into training pairs for video-language models.
The clearest example is EgoVLP. Its authors built EgoClip, a set of 3.8 million clip-text pairs drawn from Ego4D, and used it to pretrain a video-language model, according to the EgoVLP paper. They reported strong results on five downstream tasks across three datasets, including action recognition on Charades-Ego and video-text retrieval on EPIC-KITCHENS-100.
None of that would have been possible from the raw footage alone. The narrations, with their timestamps, did the work.
The same layered idea appears in Ego4D's hand-and-object benchmark. Its guidelines describe annotators reading each narrated action, then marking contact frames and drawing boxes around hands and objects. That layer covers about 116 hours and 91,002 interactions. The narration came first and made the finer labels possible.
Participant and location IDs let you test a model on people and places it has never seen. Without them, the same person can end up in both your training and test sets, and your accuracy looks better than it really is.
The UCI Human Activity Recognition Using Smartphones dataset is a good example. It records 30 volunteers doing six activities with a waist-mounted phone. Every record includes the activity label and an identifier of the subject. The creators used that ID to put 70% of the volunteers in training and 30% in testing, so the test set holds only new people.
Location and date metadata work the same way. EPIC-KITCHENS-100 uses its collection dates to test whether models trained on 2018 footage still work on footage filmed two years later. That kind of "test of time" check only works when each video carries its recording date.
Metadata is also how you prove a dataset is fit to use. It records how footage was collected, whether it passed review, and what you're allowed to do with it.
The Datasheets for Datasets paper argues that every dataset should document its motivation, composition, collection process and recommended uses. That is metadata at the level of the whole dataset, and it answers the questions a legal or procurement team will ask.
In practice, look for fields like these:
For more on judging a dataset as a whole, see our guide to what makes a dataset useful.
Ask for the schema before you ask for the price. A vendor that can't show you a field-by-field layout probably can't deliver consistent metadata either.
Useful questions include:
Firsthand publishes its answer to these questions. Its episode schema lists a meta.json for every episode with a skill ID, an anonymized site ID, a stable non-identifying participant ID, a clock domain, opening and closing calibration, calibration drift in millimeters, reject flags and a buyer-owned commercial license. The annotations include action segments with start time, end time, verb and noun, plus contact events, object lists and gaze targets.
Per its egocentric video data collection page, annotation covers actions, hand pose, objects and transcripts. Faces, plates and screens are blurred and checked by a reviewer, and data ships as RLDS, LeRobot, WebDataset or MP4 plus JSONL.
Every dataset has limits, and so does Firsthand.
Metadata is what turns hours of footage into a human activity recognition dataset a model can learn from. Action labels and timestamps tell it what happened and when. Participant and site IDs keep your tests honest. Consent and license fields keep you safe to ship. Before you buy video data, ask to see the schema, because that tells you more about the dataset than the hour count ever will.
Human activity recognition is the task of identifying what a person is doing from data such as video or motion-sensor readings, for example walking, cooking or opening a door. Models learn it from labeled examples, where each clip or sensor window is tagged with the activity and, for video, its start and end time.
The UCI Human Activity Recognition Using Smartphones dataset records 30 volunteers aged 19 to 48 doing six activities, such as walking and sitting, with a waist-mounted phone. It captures acceleration and rotation at 50Hz, tags each record with a subject ID, and is licensed CC BY 4.0.
Metadata for AI is the information that describes training data rather than the data itself. For video, that means action labels, timestamps, participant and location IDs, device and calibration details, consent records and license terms. It tells a model what to learn from each clip and tells teams whether they can use it.
Metadata is often grouped as descriptive (what something is, such as title or subject), structural (how parts relate), administrative (how it is managed and who holds rights) and technical or preservation details. The University of Texas Libraries lists three main types and places technical and preservation details under administrative metadata.
AI training data consists of raw examples, such as text, images, audio, video or sensor readings, plus the labels and metadata that describe them. For a human activity recognition dataset, that means video or sensor streams paired with action names, start and end times, and IDs for each participant and location.


Compact, ready to go anywhere
Interchangeable lens that’s upgradeable
Dual 1-inch sensors for improved clarity and low light performance
Dynamic range and 6K 360° capture
360° photo resolution at 21MP

8K 360° video recording for ultra-detailed visuals.
4K single-lens mode for traditional wide-angle shots.
Invisible selfie stick effect for drone-like perspectives.
2.5-inch touchscreen with Gorilla Glass protection.
Waterproof up to 33ft for underwater shooting.

360° photo resolution in 23MP
Slim design at 24 mm thick
Built-in image stabilization for smooth video capture.
Internal 19GB storage for photo and video storage.
Wireless connectivity for remote control and sharing.

60MP 360° still images for high-resolution photography.
5.7K 360° video recording at 30fps.
2.25-inch touchscreen for intuitive control.
USB Type-C port for fast charging and data transfer.
MicroSD card slot for expandable storage.


Try it free. No credit card required. Instant set-up.