Synthetic data is artificially generated using rules, simulations, or AI models, while real-world data comes from actual events, interactions, and observations. Synthetic data can help teams test scenarios and supplement limited datasets. Real-world data provides evidence of how systems behave in practice. For many AI projects, a carefully evaluated combination of both is most useful.
Artificial intelligence depends on high-quality data to recognize patterns, generate responses, and perform tasks effectively. However, the source and characteristics of that data can significantly influence how an AI model behaves.
One important consideration in AI development is synthetic data vs. real-world data.
Real-world data comes from actual observations, activities, and interactions. Synthetic data is artificially generated using predefined rules, statistical methods, simulations, or AI models.
Both approaches offer valuable capabilities.
Real-world datasets provide authentic examples of how people, environments, and systems behave. Synthetic datasets allow developers to create additional examples, simulate uncommon scenarios, and experiment with controlled conditions.
However, synthetic data cannot always reproduce the complexity of real-world information, and authentic datasets may contain gaps or inconsistencies.
Understanding the differences helps organizations determine which type of data best supports their AI projects.
Synthetic data is artificially generated information designed to reproduce selected characteristics, structures, or patterns found in real-world data.
Rather than recording an actual event, synthetic data represents information created through a controlled process.
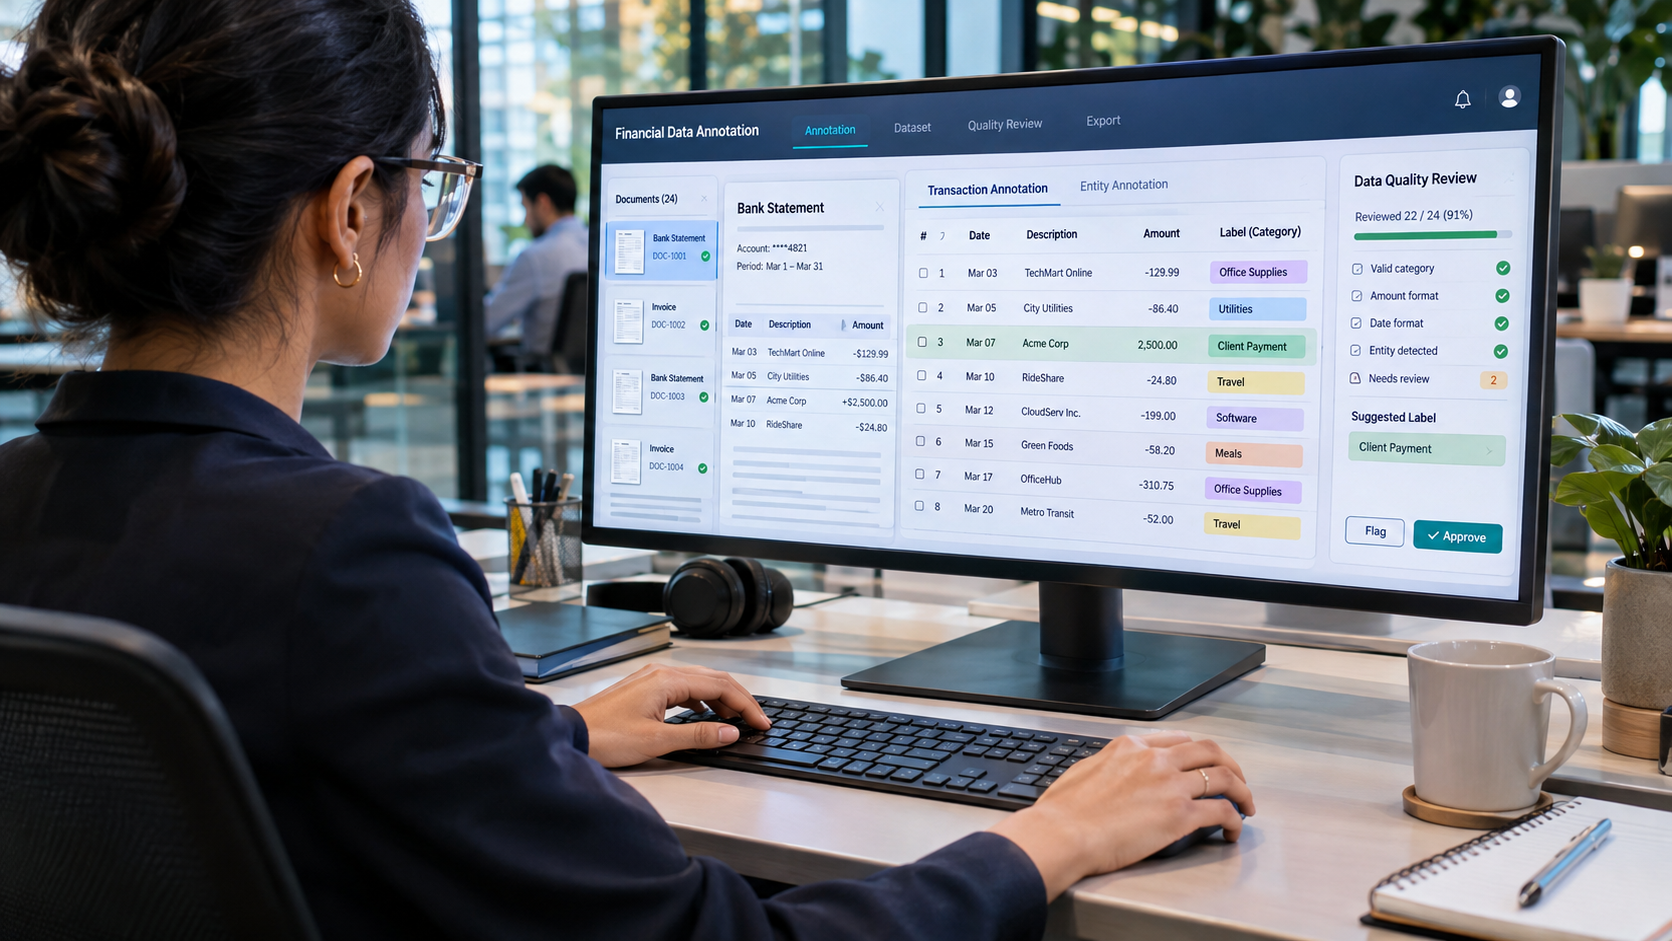
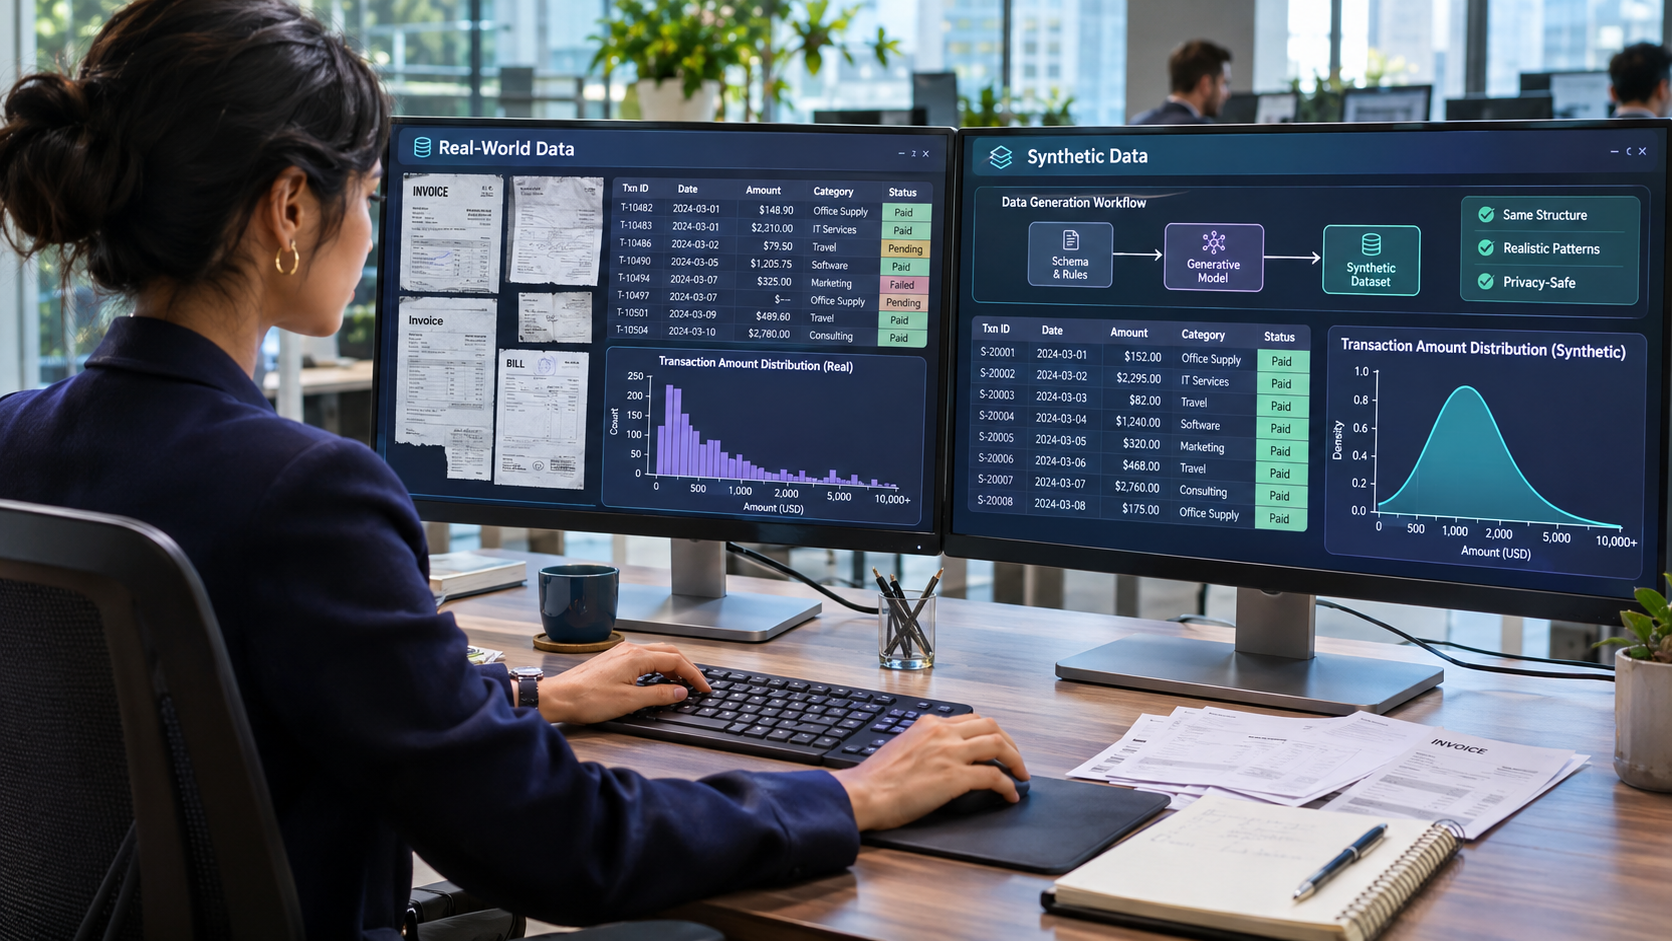
For example, a financial application might use fictional transaction records to test its categorization features.
A customer support team could generate simulated conversations covering common questions, unusual requests, and different communication styles.
The UK Office for National Statistics' synthetic data policy describes how synthetic records can reproduce characteristics of original datasets while potentially reducing disclosure risks.
The level of realism and usefulness depends on how the data is generated.
These approaches support applications such as software testing, machine learning, simulation, and dataset augmentation.
Real-world data consists of information gathered from actual events, environments, systems, and human activities.
Examples include:
Unlike synthetic datasets, real-world data reflects events that genuinely occurred.
This makes it valuable for understanding how AI systems perform under authentic conditions.
For example, real customer conversations may contain incomplete questions, spelling mistakes, unexpected requests, or complex emotional expressions.
These naturally occurring variations can be difficult to reproduce accurately through artificial generation.
However, real-world data may also contain errors, duplicate entries, sensitive information, and inconsistent formatting.
The fundamental difference is the origin of the information.
Synthetic data represents generated possibilities, while real-world data reflects observed events.
Neither is universally superior. The appropriate choice depends on the intended application.
Synthetic data generation begins by identifying what information an AI system requires.
Developers then select a generation method that can produce examples with the necessary characteristics.
Rule-based systems create records according to predefined instructions.
For example, a company could generate fictional invoices containing dates, vendor names, payment amounts, and transaction categories.
This approach provides control over the output but may struggle to reproduce complex relationships.
Simulation-based methods model environments, processes, or interactions.
Autonomous driving developers may simulate different road conditions, while robotics teams may generate scenarios involving object movement and navigation.
Simulations help developers test conditions that are difficult to reproduce consistently.
Machine learning models can learn patterns from existing datasets and generate new examples.
The research paper Modeling Tabular Data Using Conditional GAN introduced CTGAN, a method designed to address challenges associated with generating synthetic tabular data.
Generative approaches can model relationships between variables, although their outputs still require evaluation.
AI development involves more than collecting large quantities of information.
Datasets may require preparation, annotation, validation, quality assurance, and ongoing improvement.
Both synthetic and real-world data can contribute to these activities.
Real-world examples help developers understand authentic patterns, while synthetic examples can supplement missing scenarios or provide controlled testing material.
The process often involves several connected activities:
These activities are part of broader AI training data workflows.
For a detailed explanation of dataset preparation, annotation, and quality assurance, read CloudPano's guide on what AI training data services are and how they work.
A structured approach helps teams determine where synthetic data adds value and where authentic examples remain necessary.
Synthetic data offers several practical advantages.
Some AI projects lack sufficient examples of specific situations.
Synthetic generation can provide additional records for developers to test whether greater coverage improves performance.
However, more examples do not automatically produce a more representative dataset.
Certain events occur infrequently in real-world environments.
For example, a logistics system could simulate unusual delivery disruptions, while an autonomous vehicle system could test uncommon road conditions.
Synthetic data allows these scenarios to be explored in controlled settings.
Development teams often need sample data before authentic records are available.
Synthetic datasets can support interface development, software testing, and early AI experiments.
Developers can specify certain attributes when generating examples.
This makes it easier to test selected conditions or investigate potential weaknesses.
Nevertheless, artificial control cannot guarantee that every generated scenario accurately reflects reality.
Despite the flexibility of synthetic data, authentic datasets remain important.
Real-world information includes irregularities that artificial generation may overlook.
Speech recordings may contain background noise. Images may have unexpected lighting. Customer conversations may include ambiguous language.
These details are relevant when AI systems must operate outside controlled environments.
Synthetic data depends on assumptions, rules, or patterns learned from existing information.
If those representations are incomplete, meaningful relationships may be lost.
Real-world observations provide evidence of what actually occurs.
A model can perform well on simulated records while struggling with genuine inputs.
Independent real-world testing helps determine whether improvements achieved during development translate into practical performance.
Research published in Scientific Reports examining the replicability of analyses using synthetic health data demonstrates why results obtained from synthetic datasets need careful comparison with those from original data.
Synthetic datasets introduce their own challenges.
Unrealistic patterns: Generated examples may appear plausible while containing relationships that rarely occur in practice.
Limited diversity: Generation methods may emphasize common patterns and overlook unusual but important cases.
Reproduced bias: Models trained on incomplete source datasets may generate examples reflecting the same limitations.
Misleading evaluations: Testing exclusively on synthetic data can produce results that do not accurately reflect performance under real-world conditions.
These limitations make validation an essential part of synthetic data development.
Different applications benefit from different approaches.
Synthetic data is useful for building and testing systems that require realistic-looking sample records.
Examples include fictional customer profiles, test invoices, and simulated transactions.
Both types can support model development.
Real-world records provide authentic examples, while synthetic data can supplement selected gaps or introduce controlled variation.
Synthetic datasets can help researchers explore hypothetical conditions.
However, findings should be interpreted according to the assumptions used during generation.
Large language models may use both human-created and AI-generated prompt-response examples.
Synthetic prompts can expand coverage, while authentic interactions and expert evaluations provide practical feedback.
CloudPano explains this process in its article on how prompt-response datasets are created.
For specialized applications, the balance between generated and authentic examples should reflect the model's intended tasks.
Before using synthetic datasets, developers should assess whether they support the intended application.
Important evaluation areas include:
Does the synthetic dataset preserve relevant distributions and relationships found in the source data?
Does using the synthetic data improve results on the target task?
A dataset may look realistic without providing meaningful benefits during model training.
Does the dataset represent the scenarios and variations needed for the application?
Could generated examples reveal information about the original records or individuals represented in the source data?
The NIST SDNist Synthetic Data Report Tool provides an example of assessing synthetic datasets using utility and privacy-related measures.
The most useful evaluation methods depend on the dataset's format and intended purpose.
Synthetic data can potentially reduce the need to share original records, but it does not automatically guarantee privacy.
Generated examples may retain distinctive characteristics from their source datasets.
In some circumstances, those characteristics could reveal information associated with original records.
The NIST publication De-Identifying Government Datasets: Techniques and Governance discusses approaches to data sharing, including synthetic data and related privacy considerations.
Organizations should assess the characteristics of their datasets rather than assuming that artificially generated information carries no risk.
For many AI projects, a hybrid approach offers practical advantages.
Developers can begin with real-world examples to understand the task, generate synthetic records to address selected gaps, and then evaluate the model against independent authentic data.
A typical process includes:
This approach makes it possible to assess whether synthetic examples provide measurable value.
It also supports ongoing model improvement.
CloudPano's article on why AI agents need continuous evaluation explains how repeated testing can reveal weaknesses as models, prompts, tools, and operating environments change.
Continuous evaluation is especially valuable when teams regularly update their training datasets.
The comparison between synthetic data vs. real-world data is not about identifying one universally superior option.
Synthetic data provides flexibility for simulation, testing, and dataset augmentation. Real-world data captures authentic conditions and helps establish whether AI models perform reliably in practice.
Both approaches require careful preparation, quality assessment, and ongoing evaluation.
For many organizations, combining synthetic and real-world datasets offers a practical way to support AI development while maintaining a focus on measurable performance.
Synthetic data is artificially generated through rules, simulations, statistical models, or AI systems. Real-world data is collected from actual events, environments, and interactions. The main difference is whether the information was generated or observed.
Not necessarily. Synthetic data can supplement limited examples and support controlled testing. Real-world data provides authentic information and is important for evaluating performance under actual conditions. Many projects benefit from combining both.
Synthetic data may be sufficient for certain simulations or software tests. However, many AI applications still require authentic examples to evaluate how well models perform in real environments. Complete replacement should be assessed on a case-by-case basis.
No. Synthetic datasets can retain characteristics of their source data and may reveal sensitive information under certain conditions. Privacy risks depend on the generation method, source information, and safeguards used.
Businesses can use real-world examples to understand authentic patterns, generate synthetic records for selected gaps, and train models using the evaluated combination. Independent real-world testing helps determine whether this strategy improves model performance.


Compact, ready to go anywhere
Interchangeable lens that’s upgradeable
Dual 1-inch sensors for improved clarity and low light performance
Dynamic range and 6K 360° capture
360° photo resolution at 21MP

8K 360° video recording for ultra-detailed visuals.
4K single-lens mode for traditional wide-angle shots.
Invisible selfie stick effect for drone-like perspectives.
2.5-inch touchscreen with Gorilla Glass protection.
Waterproof up to 33ft for underwater shooting.

360° photo resolution in 23MP
Slim design at 24 mm thick
Built-in image stabilization for smooth video capture.
Internal 19GB storage for photo and video storage.
Wireless connectivity for remote control and sharing.

60MP 360° still images for high-resolution photography.
5.7K 360° video recording at 30fps.
2.25-inch touchscreen for intuitive control.
USB Type-C port for fast charging and data transfer.
MicroSD card slot for expandable storage.


Try it free. No credit card required. Instant set-up.