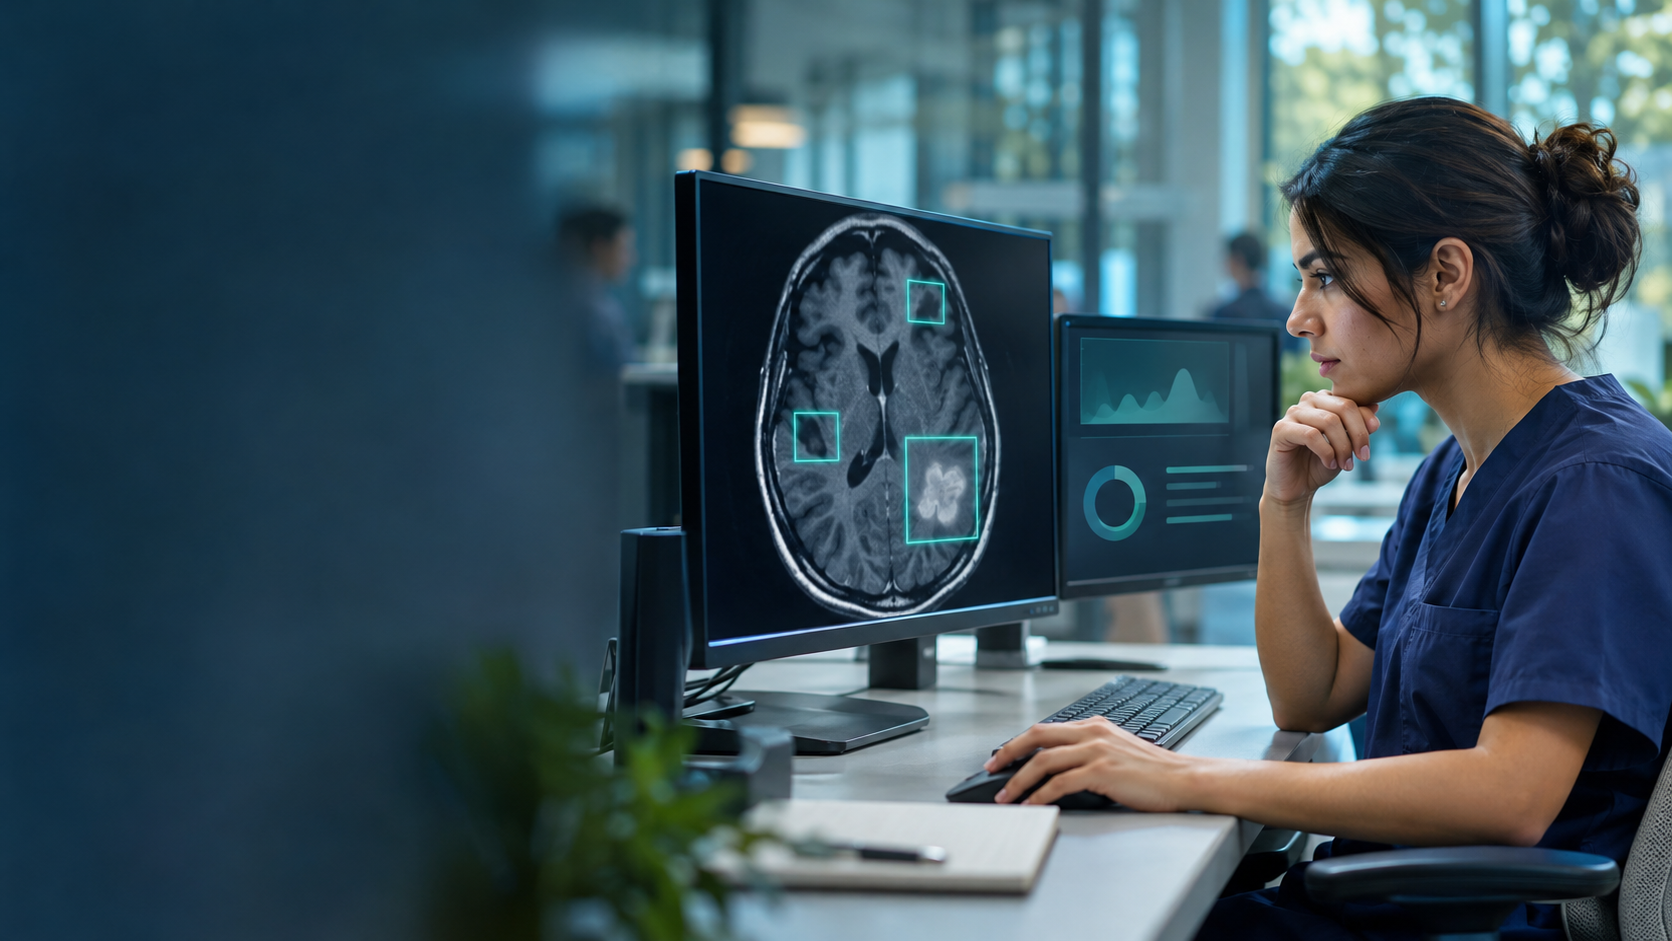
Healthcare organizations can improve data annotation practices by minimizing identifiable information, using secure labeling environments, controlling access, training annotators, and reviewing datasets for quality and privacy risks. These measures support responsible AI development, although legal compliance depends on the specific data, organizations, and applicable requirements.
Artificial intelligence is helping healthcare teams analyze medical images, organize documents, support research, and develop smarter digital tools. Behind many of these applications is an essential but often overlooked process: data annotation.
Data annotation transforms raw information into examples that AI systems can learn from. In healthcare, however, the source material may include sensitive details about real people. Building useful datasets requires attention to both the quality of the labels and the way the underlying information is handled.
Searches for HIPAA compliant data annotation often reflect a practical question: How can a team prepare healthcare information for AI while keeping privacy, security, and responsible data use in mind?
The answer starts with a privacy-first workflow, clear documentation, and careful review at every stage. None of these practices, on its own, establishes legal compliance; the requirements for a particular project depend on its circumstances.
Healthcare data annotation is the process of labeling medical or health-related information so that an AI model can recognize patterns, learn tasks, or be evaluated against known examples.
Depending on the application, annotators may work with images, text, audio, video, or structured records.
Common examples include:
Labels help models learn what features matter. But a label is only useful when it is consistently defined, accurately applied, and suitable for the intended purpose.
Privacy safeguards also matter because an annotation team may see information that never appears in the final AI application.
Healthcare datasets are different from ordinary collections of product photos or public documents.
A single image may contain an identifying overlay, a clinical note may reveal a recognizable personal story, and an audio recording may include a patient's name or location.
The consequences of careless data handling go beyond a technical mistake. People reasonably expect information about their health to be treated with care.
Teams developing medical AI therefore need to build trust through transparent processes, limited access, and accountable oversight.
The World Health Organization's guidance on AI for health emphasizes the importance of ethics, human rights, and responsible oversight across healthcare AI development.
For annotation projects, this translates into everyday questions:
Addressing these questions early helps create a more responsible foundation for AI training.
Before collecting examples, clearly define the specific AI task.
Is the project teaching a model to identify a structure in an image, extract a medical term, or classify the intent of a support request?
A clear purpose helps teams decide which information is essential and which can be excluded.
For instance, an image-labeling project may not need names, appointment details, or billing information.
Limiting the dataset at the beginning usually simplifies later review and reduces unnecessary exposure to sensitive information.
Removing unnecessary identifying details can make annotation safer.
Depending on the dataset, preparation may involve:
This work requires careful review.
Identifiers can appear in unexpected places, including file names, device metadata, written comments, spoken dialogue, and background objects.
Removing a visible name does not automatically prevent identification through other clues.
The U.S. Department of Health and Human Services' guidance on de-identification explains why information in structured fields and free text deserves close attention.
When a project requires a formal determination about de-identification, qualified specialists should conduct that assessment.
A secure annotation environment should allow authorized reviewers to complete their tasks without unnecessarily exposing source materials.
Useful features include:
The appropriate safeguards depend on the sensitivity of the information and the project's needs.
For example, a text-review task may require only short excerpts, while a medical imaging project may need a secure viewer with specialized annotation tools.
Teams should also establish clear procedures for screenshots, downloads, personal storage, messaging platforms, and external AI tools.
Even well-designed annotation platforms cannot prevent every mistake.
Annotators need to understand the task, appropriate data-handling practices, escalation procedures, and what to do when they encounter unexpected personal information.
Training should include:
When tasks require medical interpretation, appropriate domain experts should help define the annotation criteria and review challenging cases.
Well-trained annotators contribute to both stronger data quality and more consistent information handling.
Poor labels can weaken a model's performance, introduce errors, or reinforce unwanted biases.
A practical quality assurance process may include reviewing selected examples twice, comparing reviewer decisions, resolving disagreements, and periodically updating instructions.
Privacy checks should happen alongside accuracy checks.
For example, reviewers can inspect whether personal information remains in sample text, whether sensitive metadata is included in exports, or whether annotation comments contain unnecessary details.
The NIST AI Risk Management Framework encourages organizations to consider trustworthiness and risk throughout AI design, development, and evaluation.
Dataset quality and careful information handling are important parts of that wider process.
Data provenance describes where information originated, how it was collected, what permissions apply, and which changes occurred before delivery.
It helps teams understand the history of a dataset instead of relying on incomplete handover notes.
Useful documentation may include:
Documentation becomes particularly valuable when datasets are combined, updated, or reused for another experiment.
For an example from another AI data category, Firsthand's provenance and consent page describes how its collection process tracks permissions and changes.
This illustrates the value of traceable data handling, although documented provenance alone does not establish healthcare compliance.
An annotation project needs a clear ending as well as a careful beginning.
Teams should decide who can receive completed datasets, how files are transferred, where versions are stored, and when temporary copies should be removed.
Access permissions should also be reviewed when contractors leave or projects change ownership.
Retaining appropriate documentation helps teams understand how datasets were prepared without keeping unnecessary working copies indefinitely.
The voluntary NIST Privacy Framework offers a broader structure for identifying and managing privacy risks.
Its value lies in helping organizations approach privacy as an ongoing responsibility.
Privacy-first processes do not need to be complicated to be consistent.
A structured workflow can guide an AI team from initial planning to final dataset delivery.
This structure can support different annotation formats, although the specific steps should be adapted to the task.
For example, scanned documents may require text recognition checks, while medical imaging projects may need specialized review.
For projects involving AI-enabled medical devices, the FDA's Good Machine Learning Practice guiding principles provide additional background on careful AI development.
Not every annotation project involves a medical device, but the emphasis on quality throughout development is broadly useful.
Large language models introduce additional annotation formats.
Instead of marking an object inside an image, reviewers may label a prompt, compare possible answers, identify unsupported claims, or evaluate whether a response is useful.
Consider a fictional healthcare education assistant.
A team might create a question about general appointment preparation and pair it with a clear, medically reviewed answer.
This can help teach the model an appropriate response style without relying on an actual patient's private conversation.
For a more detailed explanation of the general workflow, explore how prompt-response datasets are created for LLMs.
Prompt design, answer review, deduplication, and evaluation all contribute to developing useful datasets.
Synthetic examples can also help reduce the need to expose real patient records.
However, generated content still requires accuracy and privacy checks because synthetic responses may contain errors or reproduce sensitive source material.
When comparing annotation providers, organizations should look beyond general marketing claims and focus on practical capabilities.
Useful questions include:
A provider's description of its services as “secure” or “HIPAA compliant” should not be treated as proof of suitability for every project.
Organizations should evaluate whether the provider's actual processes meet their specific requirements.
HIPAA compliant data annotation generally refers to healthcare data labeling conducted with applicable HIPAA privacy and security requirements in mind. It may involve controlled access, secure annotation environments, careful data handling, and appropriate safeguards. Whether a particular process meets HIPAA requirements depends on the organization and its specific activities.
Data privacy is important because healthcare datasets may contain sensitive information, including medical histories, diagnoses, images, and personal identifiers. Privacy-conscious annotation practices help reduce unnecessary exposure while supporting the development of accurate and reliable AI systems.
Common best practices include minimizing identifiable information, using approved annotation platforms, implementing role-based access controls, training annotators, documenting dataset origins, and conducting regular quality reviews. The appropriate measures depend on the sensitivity of the data and the intended AI application.
Yes. Healthcare organizations can work with external data annotation providers. Before sharing information, they should evaluate a provider's security practices, annotation experience, access controls, quality assurance procedures, and data-handling responsibilities. Any applicable contractual and privacy requirements should also be addressed.
Data annotation provides structured examples that help AI models recognize patterns, classify information, and evaluate predictions. High-quality labels can support applications such as medical image analysis, clinical text processing, healthcare research, and AI-powered assistants. Consistent labeling and careful validation help improve dataset reliability.


Compact, ready to go anywhere
Interchangeable lens that’s upgradeable
Dual 1-inch sensors for improved clarity and low light performance
Dynamic range and 6K 360° capture
360° photo resolution at 21MP

8K 360° video recording for ultra-detailed visuals.
4K single-lens mode for traditional wide-angle shots.
Invisible selfie stick effect for drone-like perspectives.
2.5-inch touchscreen with Gorilla Glass protection.
Waterproof up to 33ft for underwater shooting.

360° photo resolution in 23MP
Slim design at 24 mm thick
Built-in image stabilization for smooth video capture.
Internal 19GB storage for photo and video storage.
Wireless connectivity for remote control and sharing.

60MP 360° still images for high-resolution photography.
5.7K 360° video recording at 30fps.
2.25-inch touchscreen for intuitive control.
USB Type-C port for fast charging and data transfer.
MicroSD card slot for expandable storage.


Try it free. No credit card required. Instant set-up.