AI data collection services help organizations gather, structure, verify, and deliver the real-world data needed to train, fine-tune, and evaluate AI and machine learning models. Providers may collect images, video, audio, text, or sensor data using contributors, field teams, or specialized equipment. The right provider should match your required data type, scale, diversity, quality standards, consent requirements, and delivery format.
Your introduction is good, but I'd make it slightly more answer-first:
AI data collection services help AI and machine learning teams gather the real-world data their models need for training, fine-tuning, validation, and evaluation. These services can collect images, video, audio, text, and sensor data according to specific requirements, then organize, verify, and prepare that data for use in an AI pipeline.
For teams that need large volumes of specialized or diverse data, working with a data collection provider can eliminate the need to recruit contributors, manage field collection, build quality-control workflows, and organize raw data entirely in-house.
This guide explains how AI data collection services work, the types of data they collect, how they differ from data annotation, and what to evaluate when choosing a provider.
At a basic level, AI data collection services handle the sourcing side of the machine learning data pipeline: recruiting contributors or field teams, capturing raw data under specified conditions, attaching structured metadata (timestamps, device details, environmental tags, consent records), and — in most credible offerings — running the data through some form of human verification before delivery.

This is distinct from data annotation or data labeling, which typically starts after data already exists and focuses on adding labels (bounding boxes, transcriptions, sentiment tags) to it. Many providers offer both collection and annotation as a combined pipeline, but they solve different problems: collection answers "where does the raw data come from," and annotation answers "how do we make it usable for supervised learning."
Model architecture gets a lot of attention, but data quality is increasingly treated as the bigger lever on real-world performance. This is the core argument behind the "data-centric AI" movement, which holds that for many production systems, improving the data — its diversity, accuracy, and representativeness — yields larger gains than further tuning the model itself, a view discussed at length in outlets like MIT Technology Review covering the shift from model-centric to data-centric development.
Poorly collected data creates problems that surface only after deployment: models that perform well on a narrow test set but fail on edge cases, lighting conditions, accents, or demographics that weren't represented during collection. This is why real-world capture conditions — not just volume — matter so much. A dataset of a million images shot under identical studio lighting is less useful for an autonomous driving model than a smaller, more varied set captured across weather conditions, times of day, and geographies.
According to a Grand View Research report on the data collection and labeling market, demand has grown alongside enterprise AI adoption across computer vision, natural language processing, and autonomous systems use cases.
Different model types require fundamentally different raw material. The most common categories include:
Used for computer vision tasks: object detection, facial analysis (subject to strict consent requirements), scene understanding, and autonomous navigation. Real-world video capture — recorded in authentic environments rather than staged studio conditions — tends to produce models that generalize better to production conditions, since it naturally includes the visual noise, occlusion, and variability models will encounter after deployment.
Used for NLP tasks such as sentiment analysis, translation, and large language model fine-tuning. Collection here often involves sourcing conversational transcripts, domain-specific documents, or multilingual corpora.
Used for speech recognition, voice assistants, and audio classification. Accents, background noise, and device microphone variation all need representation.
Used for robotics, predictive maintenance, and industrial AI. This includes LiDAR, accelerometer, temperature, and other structured sensor streams, typically paired with timestamped metadata.
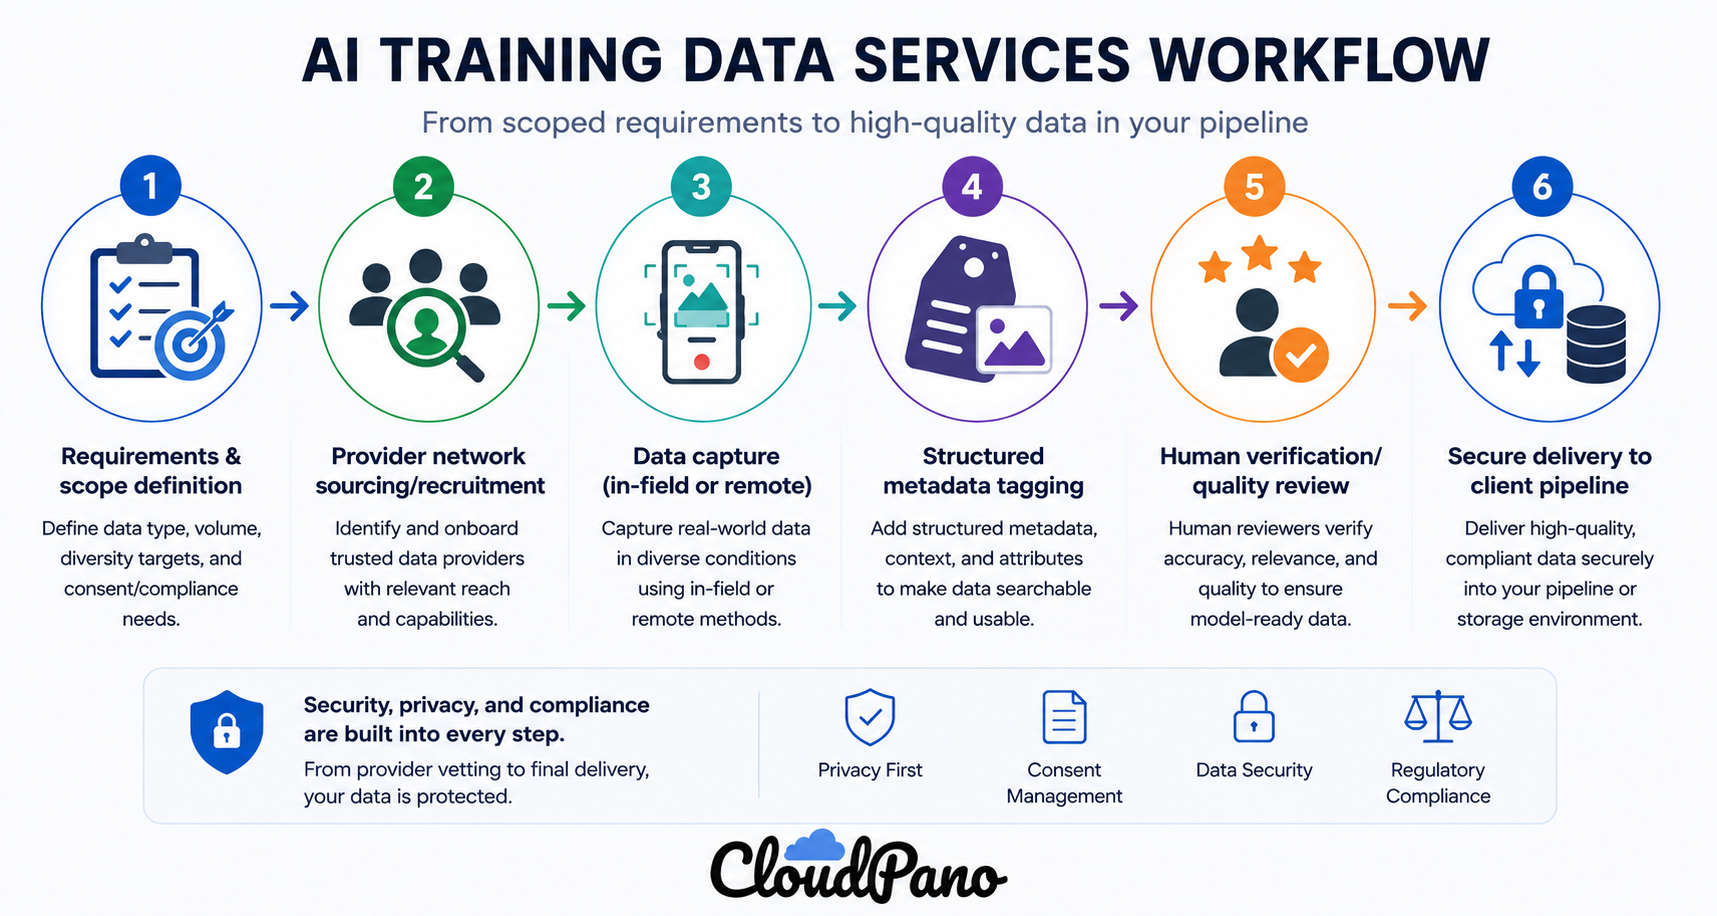
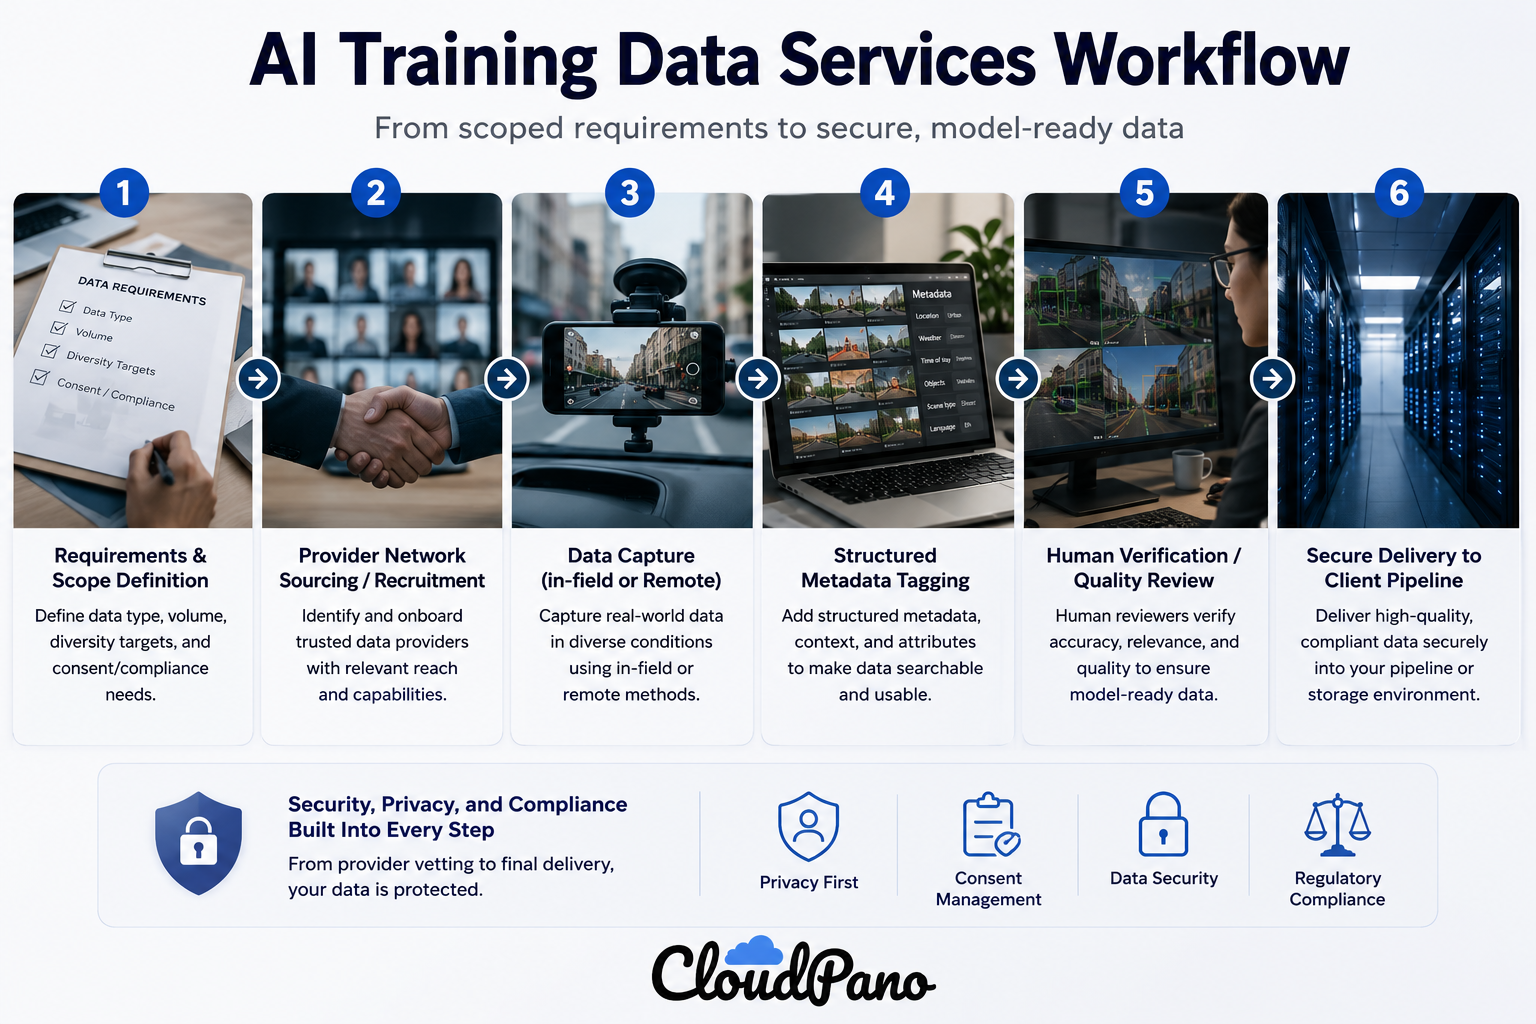
A well-run data collection engagement generally follows a consistent workflow, regardless of data type.
In practice, many mature ML programs use a blend: outsourced, real-world collection for the bulk of training data, synthetic data to fill gaps for rare edge cases, and small amounts of in-house collection for highly proprietary or sensitive scenarios.
A few questions are worth asking any vendor before committing:
Automated quality checks — deduplication scripts, basic metadata validation, format checks — catch a portion of issues, but they miss the kind of contextual errors a human reviewer catches immediately: a mislabeled location, an audio clip cut off mid-word, a video shot in conditions that don't actually match the brief. This is why human verification remains a meaningful differentiator between providers rather than a "nice to have" — it's often the difference between a dataset that's technically delivered and one that's actually usable without significant client-side rework.
Firsthand provides custom real-world data collection for AI and machine learning teams, including video, images, audio, text, and multimodal sensor data. Collection programs can be designed around specific environments, tasks, devices, languages, demographics, conditions, and edge cases.
Firsthand has a particular focus on first-person or egocentric data for embodied AI, robotics, and multimodal models. Depending on the project, collection can include synchronized video, depth, audio, motion, pose, and other sensor streams.
For AI teams that need data beyond what is available in public or off-the-shelf datasets, a custom collection program can be designed around the model's actual deployment requirements.
AI data collection services help organizations gather, organize, verify, and deliver the real-world data needed to train, fine-tune, and evaluate AI and machine learning models. Depending on the project, providers may collect images, video, audio, text, or sensor data while ensuring the data meets quality, consent, and formatting requirements before it enters a training pipeline.
Data collection focuses on creating or sourcing raw data, while data annotation adds labels or classifications to existing data. For example, collecting hours of driving footage is data collection, while drawing bounding boxes around vehicles in that footage is data annotation. Many providers offer both services as part of a complete training data pipeline.
Most providers can collect multiple data types, including: Images for computer vision models Video for robotics and autonomous systems Audio and speech recordings Text and conversational datasets LiDAR and other sensor data Multimodal datasets that combine several data streams The exact capabilities depend on the provider's contributor network and collection infrastructure.
Real-world data exposes models to the lighting conditions, backgrounds, accents, weather, devices, and edge cases they'll encounter after deployment. While synthetic data can help fill gaps, production AI systems generally perform better when they're trained on diverse, authentic data collected under realistic conditions.
A typical project follows six steps: Define the collection requirements. Recruit contributors or field teams. Capture the required data. Add structured metadata. Perform quality assurance and human verification. Deliver the finished dataset in the client's preferred format. This workflow helps ensure the collected data is usable immediately rather than requiring extensive cleanup afterward.


Compact, ready to go anywhere
Interchangeable lens that’s upgradeable
Dual 1-inch sensors for improved clarity and low light performance
Dynamic range and 6K 360° capture
360° photo resolution at 21MP

8K 360° video recording for ultra-detailed visuals.
4K single-lens mode for traditional wide-angle shots.
Invisible selfie stick effect for drone-like perspectives.
2.5-inch touchscreen with Gorilla Glass protection.
Waterproof up to 33ft for underwater shooting.

360° photo resolution in 23MP
Slim design at 24 mm thick
Built-in image stabilization for smooth video capture.
Internal 19GB storage for photo and video storage.
Wireless connectivity for remote control and sharing.

60MP 360° still images for high-resolution photography.
5.7K 360° video recording at 30fps.
2.25-inch touchscreen for intuitive control.
USB Type-C port for fast charging and data transfer.
MicroSD card slot for expandable storage.


Try it free. No credit card required. Instant set-up.